Agentic engineering you can verify.
Move beyond supervising agents to reviewing outcomes.
From spec to reviewed pull request, with the record. Aveto turns a paragraph into a tested, security-reviewed pull request, run by 28 specialist agents in your own Claude Code session on the plan you already pay for. You approve one Charter at the start and review the result at the end.
$node execution/install.mjs <your-repo>
- Charter approvedowner, by hash
- Scope reviewengineering-manager
- Tech specsoftware-architect
- Buildfrontend-developer
- Code reviewindependent reviewer
- QA evidenceqa-evidence
- Security reviewsecurity-privacy
- Release gaterelease-manager
- Deploy + rollback gatecloud-deployment
- Live checksproduction-verification
- Pull requestyou review and merge
Intake, scope, architecture, implementation, independent QA and security review.
Plan, validate, then deploy to Azure, AWS or GCP — validation never self-certified.
Production verification, auto-rollback on regression, on-call and customer response.
Why now
The code was never the hard part.
An agent writes the feature in minutes. What it cannot do alone is everything that makes the feature safe to ship — the architecture review, the verification by someone who didn't write it, the security pass, the release gate. That process is what separates a demo from production, it lives inside large engineering orgs, and it never shipped with the models.
of developers say they do not fully trust AI-generated code to be functionally correct.
Developer survey, 2026of AI-written code clears review unmodified — against 84% for the code a person wrote.
Industry analysis, 2026of AI-written changes still require manual debugging in production — after passing QA and staging.
Survey of 100 engineering directors and VPs, 2026of agent pilots never reach production at all. The gap is rarely the model — it is everything between a working demo and a change someone will sign.
Industry analysis, 2026How it works
One approval at the start. One review at the end.
Not guardrail text an agent is asked politely to follow. Structural properties of the lifecycle, each producing an artifact you can hand to someone who wasn't there.
- 1AskA paragraph, free-form.
- 2IntakeChecked against your recorded safety invariants. A conflict is refused and no slice opens.
- 3CharterOne document: scope, budget, models, permissions. Approved by its hash.you
- 4BuildSpecialist agents, each with its own tools. The verifier never wrote the code.
- 5VerifyCode review, QA, security. A failed gate goes back, never forward.
- 6ReleaseA gate by risk tier, a deploy, and a rollback rehearsed first.
- 7ReviewA pull request and the run's record. You merge.you
It refuses work it shouldn’t build.
Intake checks a request against your recorded safety invariants and blocks a conflict, naming it and offering a safe reframe. Given a request to auto-purge user data with no confirmation, a run stopped before any code was written.
The verifier never wrote it.
QA, security and the release gate are separate roles from the one that wrote the code, and a deploy agent cannot mark its own plan validated.
One test, so an example and not a rate: in a spike on a copy of the support agent, a second model’s blind review found a planted bug that a review by the same model family missed.
The record names who decided.
Each run keeps its Charter hash, who approved it and when, its spend against a hard cap, and a hash-chained event log. Every run is listed, including what its records leave out.
What you can do
Five things, and how far each is proven.
Turn one paragraph into a working service.
StreakKeeper was built from a one-paragraph brief, from discovery through a tested, shipped service, with every stage independently reviewed. Shown once. One small app.
Add a feature and get it back reviewed, tested and security-checked.
Every run ends in a pull request after independent QA, a security pass and a release gate. Seven traced slices across two apps, and thirteen more on a third built in public. Shown repeatedly. The merge stays yours.
Ship an AI feature with the bar set before the test.
Our own support agent’s judge refused 24 of 24 questions the docs do not answer and kept 16 of 19 that they do, on a set it had never seen. Four earlier checks failed and are on the record. It now runs as a live public service: scored once on 20 new questions it refused all 10 it should and kept 8 of 10 answerable. Shown twice, narrowly: both second bars were passed with no margin (by one question, then exactly at the bar).
Stop watching the agent.
You approve one Charter by its hash, get a notice at each stage, and review at the end. Nothing outside the Charter happens without asking. Shown twice. A person still starts each run.
Find the risk in a codebase you did not build.
Assessment mode reviews a repository on a read-only copy, with two model families as reviewers and a different family as judge, and writes a report. It records and reviews; it does not certify. On three repos with bugs planted by a separate agent, the reviewers found between 2 and 6 of 6, and missed small edge-case bugs; on a sample of 30 findings, about three in four were confirmed, by models and not yet by an owner. Pilot results. Four small repos, one not ours. Runs as a Claude Code plugin.
Try it
Ask Aveto’s docs, live.
The support agent Aveto built about itself, running on Azure. It answers with passages copied word for word from these docs, with file and line numbers, or says the docs do not answer. A model only decides whether the passages answer. Nothing on the page is written by one.
1. Open it
The first load after a quiet spell takes about half a minute.
2. Ask something the docs answer
Click one of the first three suggestions. You get quoted passages, each with its file and lines.
3. Ask something they do not
Click “Does it support right-to-left languages?” The app says so instead of guessing.
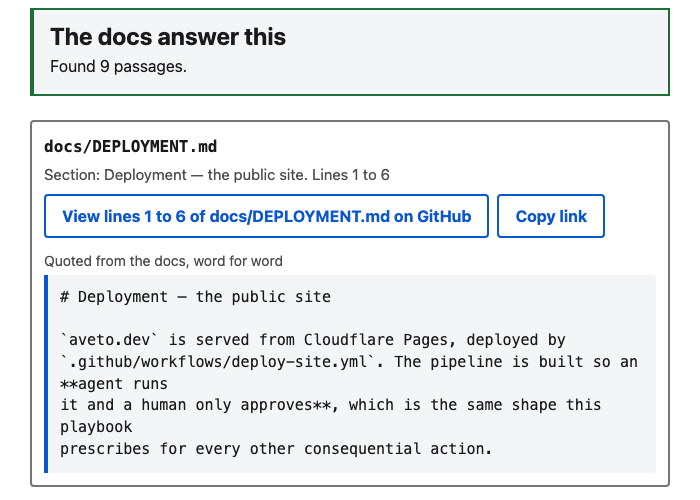
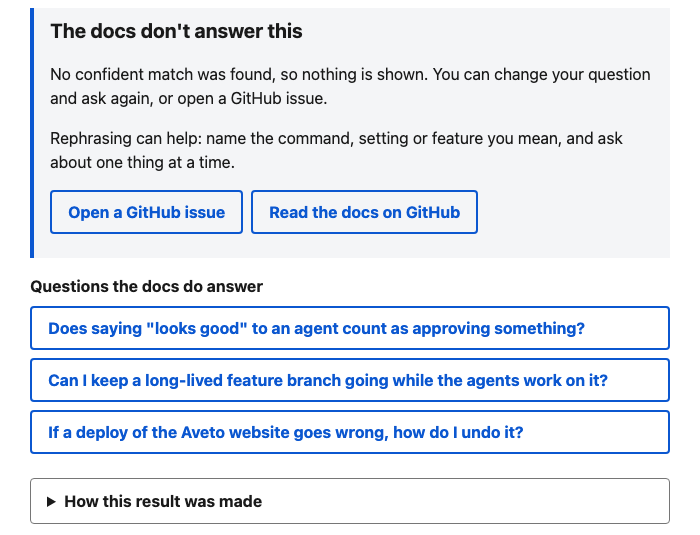
Screenshots of the live app taken on 2026-10-27.
Unanswerable or tricky questions refused with no passage, on 20 questions it had not seen.
The full result is publicAnswerable questions that got a passage from a listed source. Exactly the bar, with no margin.
Two got “no confident match”Tests pass (668 before). No serious accessibility issue on five views. Touch devices not tested.
Its Charter and record are publicFirst load after idle. A warm answer took about 1.4 s (median of six), a question about $0.0086, and a rehearsed rollback served again in about 65 s.
Scorecard: counts are raw totals since the last restart, never what was askedBefore you use it
- It is early. Ten answerable questions cannot tell “meets 80%” from “a little below it.”
- Your question and the passages found are sent to Anthropic, which makes the model. The service does not store your question, so please do not put personal information in it.
- It keeps a scrambled form of your address, the time and the outcome for 7 days, and runs in the United States.
- Limits: 10 questions an hour, 500 characters, and a pause for the day after about 33 questions (an estimate). Day limits reset when the service restarts.
Built by Aveto, in public, under a Charter one person approved by its hash, including the three accounting flaws found after launch. The record is in aveto-support. Every run, read from its own records.
What it runs on
A subscription to build. An API for what you run.
Aveto builds on the coding agent plan you already have. The product it builds pays for its own model calls, and you approve those in the Charter.
supported
optional trial
in use
not supported yet
The team
Twenty-eight specialists, not one generalist.
One agent asked to build a product makes every decision from the same context, with the same blind spots. Aveto splits the work into 28 written briefs, each with its own scope, its own tools and one artefact it must hand to the next. They ship in the repo.
Shape the work6 roles
- Orchestrator
- Market Researcher
- Engineering Manager
- Product Manager
- UX Researcher
- UI Designer
Design and build7 roles
- Software Architect
- Backend Architect
- Frontend Developer
- AI Engineer
- ML Engineer
- Analytics Engineer
- Data Analyst
Verify — none of these wrote the code5 roles
- QA Evidence
- Security & Privacy
- Compliance Reviewer
- AI Governance
- Data Governance
Ship it3 roles
- Release Manager
- Cloud Deployment
- Tech Writer
Run it — the part most tools skip7 roles
- Production Verification
- Site Reliability Engineer
- On-call Engineer
- FinOps
- Post-Launch Learning
- Customer Success
- Customer Support
The span
The record doesn't stop at the merge.
Spec-driven tools end when code lands. Deployment platforms begin when an artifact appears. Aveto carries one identity-attributed record across all three seams, as far as those tools’ own documents show.
Cloud-agnostic by gate, not by rewrite.
Aveto doesn’t rebuild your deployment engine; it wraps the one you already trust. Azure is proven. AWS and GCP are planned and not tested.
After the deploy is still on the record.
Production verification checks the live service against the invariants the spec named, not just a health ping. Customer replies are drafted, never sent: a human authorizes the message.
Evidence
Validated on live runs, not a slide.
Slices carried to merged pull requests on a reference app, a second app built from a one-paragraph brief, and a security gate that stopped its own release.
Runs recorded for the support agent, each with its Charter hash, spend and review. Some records leave things out, and the page says which.
aveto.dev/runs, read from the run recordsTests pass on the latest run (668 two runs before), with the new tests failing on the old code first.
runs/result-page-clarity, test count recordFor a rehearsed rollback to serve the previous version again. One sample, run before release.
runs/result-page-clarity, rollback rehearsalPull requests reviewed blind by a second model. The trial plans five, so the result is provisional.
docs/review-trial, four recordsThe runs correct themselves
Security review found a finished slice listening on every network interface, proved it across the LAN, and sent the work back. The same flaw was then fixed in the older app it came from.
Hard cases, tested neutrally
Shown an unsafe ask, it refused at intake. Shown an impossible one, it bounded the failure and escalated without weakening a gate.
It failed four of its own checks, and said so
Four pre-registered checks on the support agent failed and were recorded as results. A later judge then refused 24 of 24 unanswerable questions and kept 16 of 19 answerable ones, passing the second bar by one question.
One approval, then a review
A real run landed a tier 3 gate and opened a pull request after one typed message. Its own code review caught the run’s permission rules about to ship in a tracked file.
The record
Built to be handed to someone who wasn't there.
Every standard below asks a version of the same question — who authorized this, what did the system decide, and was that consistent with policy. Aveto's artifacts answer it by construction, because they were produced at the moment the decision was made rather than reconstructed afterwards.
Who it's for
For everyone shipping without a safety net.
The software matters, and nobody else stands between a mistake and production.
Solo founders and small teams
You are the architect, the reviewer and the on-call. Aveto is the colleagues you would have had at a company ten times the size.
Trigger · the first paying customerEngineers outside big tech
You know exactly what a real review process looks like. You just don't work somewhere that runs one.
Trigger · the change you can't get wrongTeams outgrowing what they can hold
Shipping faster than anyone can still keep the whole system in their head, and feeling the first things slip through.
Trigger · the first production incidentWhat it has built
What Aveto has built, and what it has not.
Honest limits
Where it costs you, and where it isn’t proven.
The validation matrix in the repo lists what isn’t proven, so this page does too.
It spends real tokens.
The 13 runs recorded in aveto-support (2 to 31 stages each) processed 0.6M to 47M tokens apiece, mostly cache reads. That counts subagent stages only and is not a bill. It is the price of every stage forming its own judgement, and why a budget is checked before each step.
Small changes do not need this.
Running a one-line fix through nine gated stages is theatre. The Engineering Manager compresses the pipeline for small slices and records why.
Least-privilege binds conditionally.
Per-role tool restrictions take effect only when the orchestrator session runs inside the product repo. Run it from elsewhere and you get capable agents with unrestricted tools.
Not yet proven.
Production SLOs, enterprise multi-tenancy, and a real model running unattended at scale. What has run: real Azure deploys of the support service, a live smoke test, and a production-verification stage. A real model decides one question at a time inside that live feature, behind a $10 monthly limit.
The newest evidence is small.
The first four Process v2 runs each needed the owner for something beyond the first Charter approval. The latest run recorded no questions after the Charter, but the record cannot see prompts the app itself shows. The judge’s two gates passed with no margin, and retrieval finds the right file for 79.2% of answerable questions, just under its own bar. Spend limits reset when the service restarts, so the $10 monthly limit is the only lasting cap. The service uses Anthropic’s API under its commercial terms, which no agent read, and the page asks visitors not to enter personal information. A person still starts each run and decides the merge. Review mode for an existing codebase is planned, not built.
From the course to your repo
Anthropic teaches the AI‑native SDLC. Aveto installs it.
Anthropic’s AI-Native SDLC Playbook course walks through six stages in about an hour. It teaches the practice. Aveto is that practice as software, installed into your repo on the Claude Code plan you already have.
intent.md.intent.md as a one-page template. Give it a one-line ask and it drafts the file, marking every guess (inferred) until you confirm.CLAUDE.md, parallel sessions and subagents.Course stages summarised from its public outline. Aveto is independent and is not affiliated with or endorsed by Anthropic.
Common questions
Straight answers.
Is this a coding agent?
No. Aveto directs the agents you already use rather than replacing them. It sits a layer above the worker; today that worker is Claude Code.
Do I have to approve every step?
No. You approve one Charter at the start: the models, data processors, safety-control changes, permissions, budget and end actions the run may use, approved by its hash. The run is built to ask nothing after that; it stops only for an action the Charter does not name, for spend past its hard cap, or for a credential. At the end you review what was done under each line. The default Charter allows no merge, no deploy and no send: a run ends with a pull request for you. An approval typed in another session does not count, and an agent’s review is never a person’s approval. Seven runs have used a Charter (five on the support agent, two on a small test app); early ones still stopped to ask about a budget set against the wrong limit, which the latest pack fixed.
Is code review part of it?
Yes, as a layer around the review Claude Code already provides, not a new reviewer. Every Charter run reviews its own diff with a reviewer that did not write it, sets a risk tier (safety text, permissions, hooks and CI are always high), limits fix-and-review rounds to three, and records each finding as fixed, rejected or intentional. The playbook is docs/CODE_REVIEW.md.
Why a subscription instead of an API key?
Because it changes who carries the cost. Aveto never resells inference: it runs on the Claude Code plan you already pay for, so it adds no separate API bill. The scarce resource is that plan’s usage window, and a long run counts against it, which is why every stage is costed before it spends and written to disk as it goes. What it runs on, part by part, is in the table above.
Can I use it with Cursor, Codex or Copilot?
Not yet. Aveto’s run rules live in an AGENTS.md file that tools such as Codex, Cursor and Copilot can read, but the agents, hooks and commands that enforce them are built for Claude Code only. A second adapter is on the backlog and starts when there is a real need. Codex is used today only as an optional, manual second reviewer.
Is the live chat an AI agent?
No. The live chat is a small app Aveto built. It finds passages in the docs, one model call decides whether they answer the question, and it shows the passages word for word or says the docs do not answer. It never writes text of its own and takes no actions. What is autonomous is the build: agents built and released it under a Charter anyone can read.
Our agents already run under scoped credentials — isn’t that enough?
Scoped credentials answer a different question: what an agent is able to touch. They say nothing about whether a particular action was authorized, or what was left behind. In an access log, a deploy a named human approved and a deploy nobody saw look identical, because both were permitted. Permission is a capability boundary; accountability is a record of who decided, when, and against which rule. Aveto assumes your credential scoping is already correct and adds the record on top.
How is this different from other tools?
They sit at different layers. Spec-driven tools structure how software gets written, and toolkits such as ECC make an agent work better with libraries of skills, hooks and memory. Aveto governs whether the work can be trusted: every stage is costed before it spends, the agent that verifies never wrote the code, gates fail closed, and a named human approves one Charter by its hash and reviews the result. The trade is breadth: Aveto is narrower, Claude Code only, built for one person on one subscription. It can be used alongside the others. Aveto is independent and not affiliated with ECC or Anthropic.
Does this work for a team, or an enterprise?
Today it is built for one person on one subscription, and that is where it is proven. Each developer running their own slices on their own subscription works now. Shared gates across a team, a run inventory spanning developers, and the conformity export an auditor asks for are on the roadmap, not shipped; a read-only page of every run exists at /runs. The validation matrix in the repo marks exactly what has and hasn’t been run at that scale.
Which clouds are supported?
Azure is the one proven end to end: the live demo runs on it, deployed by an Aveto run. AWS and GCP are planned, not tested. Each would wrap the deployment engine you already use rather than replacing it.
What happens when a deployment goes wrong?
Production verification checks the live service against the invariants the spec named, and the rollback plan approved at spec review is the one that runs, with no second approval round trip because that decision was already made. In the last two releases the rollback was rehearsed before release: the previous version served again about 65 to 70 seconds after the command, then the new version was restored. That is two samples, not a guarantee.
The documents
The specs are the product.
There is no hidden implementation. The specs below are the system — agents are generated from these files and the gates are enforced from them. Read the rules before trusting the claims.
Let the agents do more.
Aveto is open. Point the installer at a repo and it writes one least-privilege agent per role, the gates, and the commands to run a slice — on the Claude Code subscription you already have.